Overview
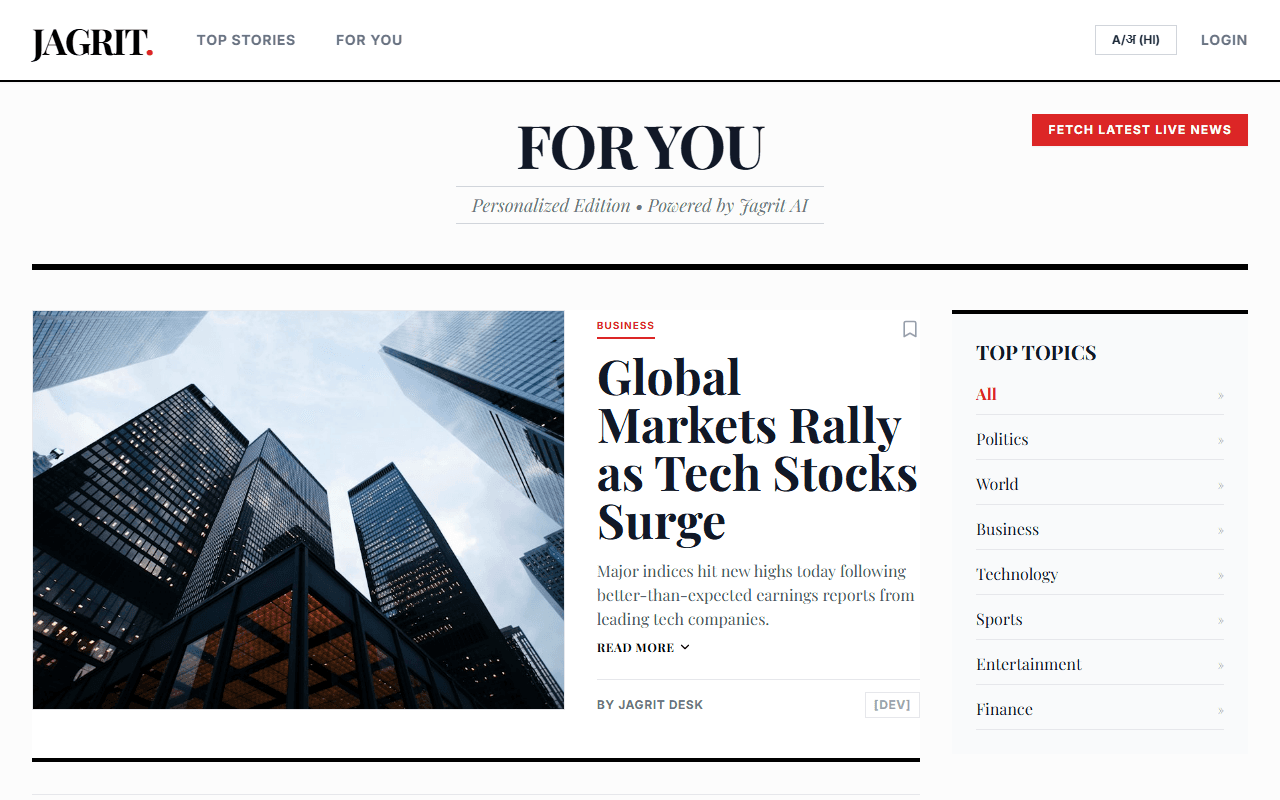
Jagrit is a bilingual news platform designed for Hindi and English readers. It ingests live content from RSS feeds and news APIs, translates between languages using Gemini, ranks personalized feeds using XGBoost, and offers RAG-based Q&A on article content. The system includes a PyTorch NRMS model for offline recommendation evaluation.
The Problem
Hindi news aggregation typically requires separate tools for translation, ranking, and Q&A. The goal was a single platform where a reader can browse live bilingual news, ask questions about articles in natural language, and receive a personalized feed — with the ranking system evaluated against established ML benchmarks.
My Contribution
Built the ingestion pipeline, translation layer, Kafka-Redis feature store, XGBoost ranker, RAG Q&A system, and the offline NRMS evaluation pipeline with AUC and nDCG metrics. Implemented the three-tier fallback architecture for feed resilience and the replay-based CTR simulation for offline evaluation.
Architecture
Content Ingestion
RSS feeds and news APIs are polled on a schedule. Normalized articles are stored in MongoDB. Kafka handles asynchronous processing and fanout to downstream consumers.
Translation & Q&A
Gemini handles Hindi↔English translation for article content and user queries. The RAG pipeline retrieves relevant article segments before passing context to the LLM for Q&A responses.
Feed Ranking
XGBoost ranks candidate articles using features from the Redis feature store (click history, category affinity, recency signals). Feed ranking runs at request time using cached features.
Offline Evaluation
A PyTorch NRMS (Neural News Recommendation with Multi-head Self-attention) model is trained and evaluated offline using AUC and nDCG metrics. CTR simulation uses a replay-based approach on historical interaction logs.
Three-tier Fallback
Primary feed: personalized XGBoost ranking. Fallback 1: category-based trending articles. Fallback 2: chronological ingestion order. This ensures the feed is always populated even when personalization data is sparse.
Engineering Decisions & Tradeoffs
XGBoost for production ranking vs. NRMS for offline evaluation
Rationale: XGBoost serves ranking at low latency from a Redis feature store. NRMS is evaluated offline to benchmark neural approaches without the deployment complexity of serving a PyTorch model at request time.
Tradeoff: NRMS offline metrics are not directly comparable to XGBoost production ranking — they use different feature sets and evaluation conditions.
Replay-based CTR simulation
Rationale: Real production CTR data from a new platform would take months to accumulate. Replay simulation using historical patterns allows earlier model evaluation.
Tradeoff: Simulated CTR does not reflect true production user behavior. Results are clearly labeled as simulated.
Challenges & Solutions
Feed cold-start for new users without interaction history
New users fall through to the fallback tiers automatically. Category preferences collected during onboarding seed the feature store to accelerate personalization.
Latency of Gemini translation on article ingestion
Translation runs asynchronously via Kafka consumers after ingestion. Articles are served in the original language immediately, with translated versions appearing as the async job completes.
Evidence & Results
- ›Bilingual news feed with live ingestion from RSS and news APIs
- ›XGBoost ranker with three-tier fallback for cold-start and sparse users
- ›NRMS model evaluated offline with AUC and nDCG metrics
- ›RAG-based Q&A on article content using Gemini
- ›Note: offline metrics and simulated CTR are not production performance figures